Four ways to retrieve.
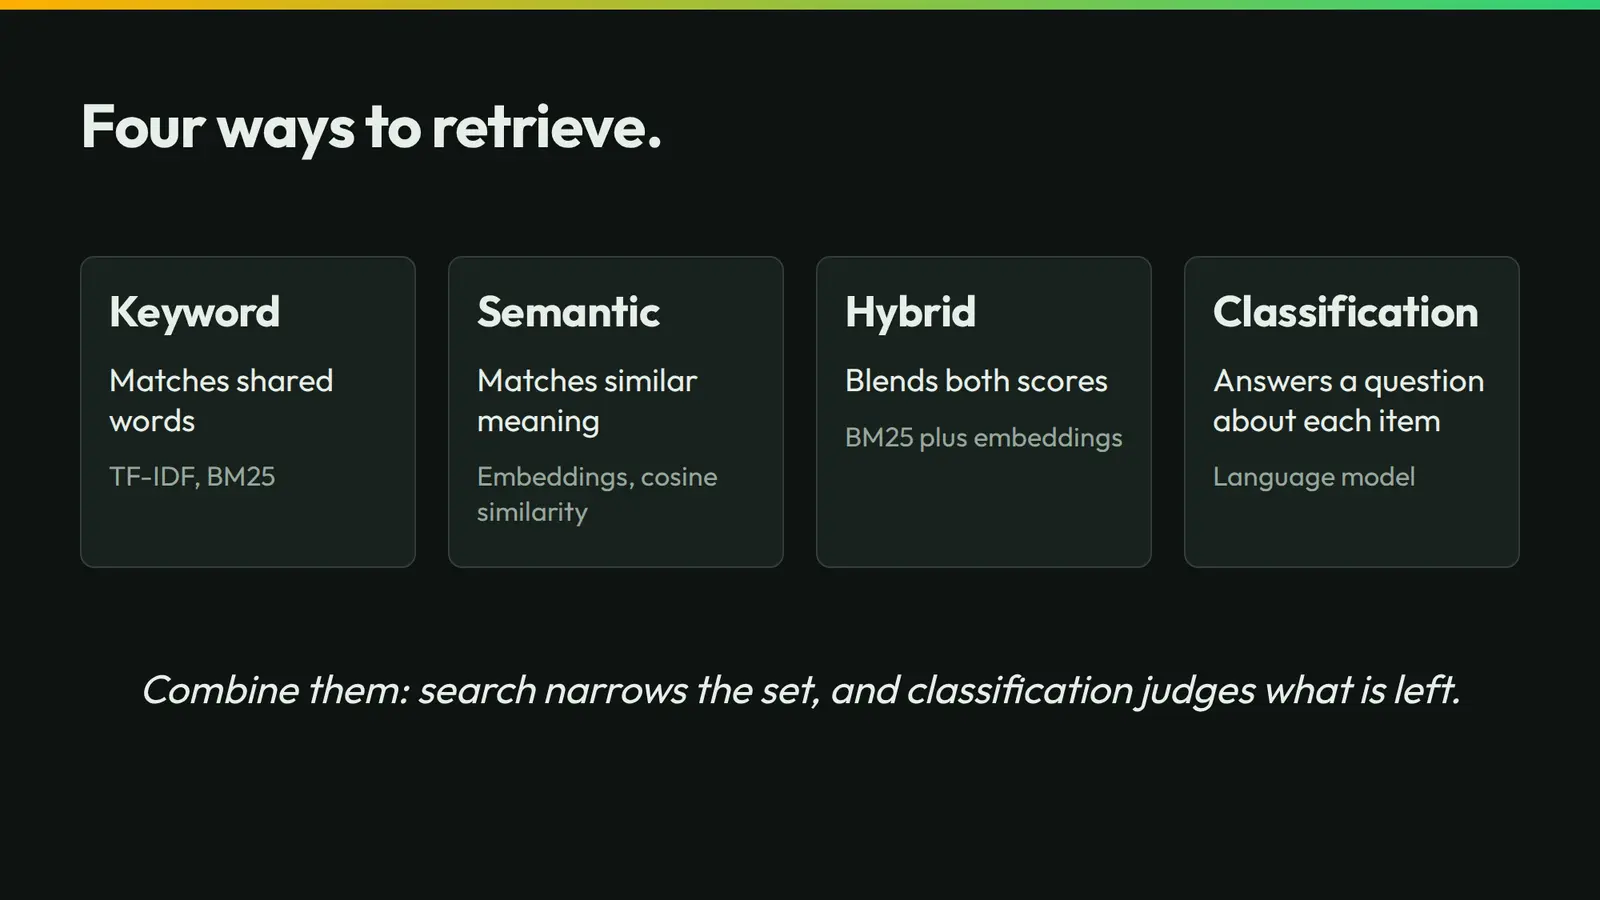
Keyword search matches shared words. TF-IDF and BM25 work this way. Semantic search matches similar meaning. Embeddings work this way. Each text becomes a list of numbers, and close lists mean close meaning. Hybrid search blends the two scores.
Classification asks a question about each item. Should it stay? How well does it fit? Which tags apply? A language model reads the item and answers. Each answer carries a probability.
The strategies combine. A cheap search narrows a large collection. Classification then judges the shortlist.
Classification can also stack on itself. Ask a coarse question first. Then ask finer questions of the fewer items that pass.
Cost grows with the number of items judged. Keyword and semantic search look items up in a prebuilt index. Classification sends every item it judges to a language model. Narrowing first keeps the cost affordable.
Combine them: search narrows the set, and classification judges what is left.
On GitHub: github.com/botassembly/beatles-bench