Beatles Bench scores the field.
The bench asks every system the same 1,501 questions. The hard set holds 505 of them, such as word traps and two-step questions. The easy set holds the other 996.
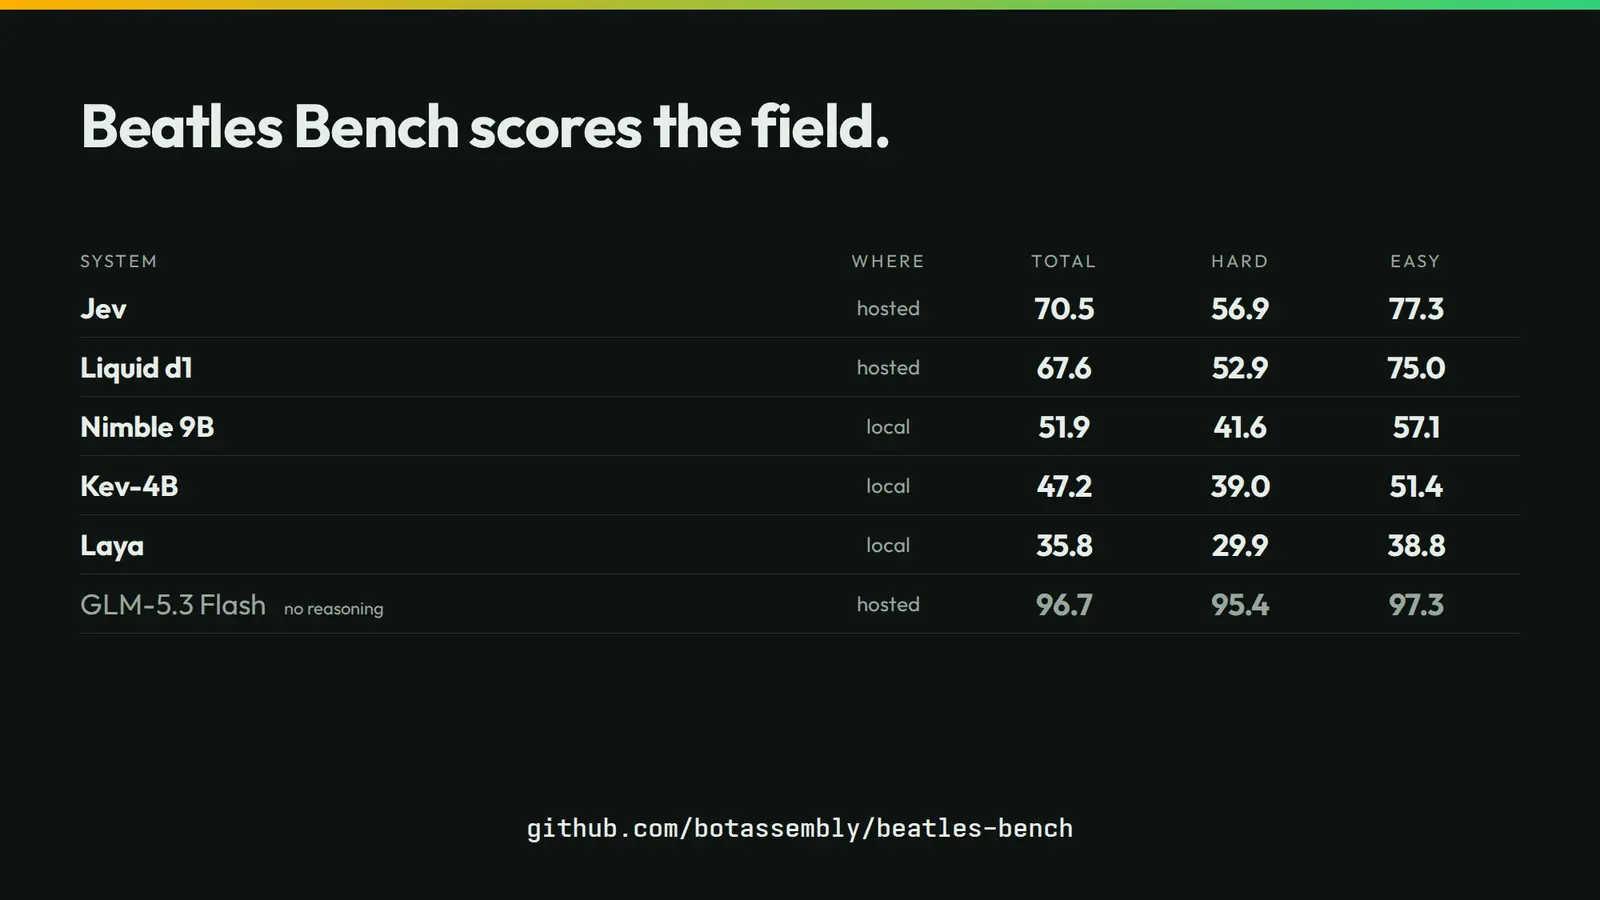
Jev leads the decision models. It gets 70.5% of all the questions right and 56.9% of the hard ones. Liquid d1 gets 67.6% and 52.9%. Nimble 9B gets 51.9% and 41.6%. Kev-4B gets 47.2% and 39.0%. Laya gets 35.8% and 29.9%.
Jev and d1 sit close, so the bench compares them question by question. It counts the questions only one of them got right: Jev alone right on 191, d1 alone on 140. A gap that wide is unlikely to come from chance.
GLM-5.3 Flash is a general language model, run with no reasoning. It gets 96.7% and 95.4%. The slide grays it out as the yardstick. It is not a decision model.
OpenAI announced its Decisions API on 2026-09-29. The bench has not run it, so it has no row.
The bench is open source. The repository holds the songs, the questions and their right answers, and a saved recording of every answer. The data is CC BY-SA 4.0.
The numbers come from the bench's accuracy table.
git clone https://github.com/botassembly/beatles-bench
cd beatles-bench./run.shexport THINKTHEN_BASE_URL=https://your-server/v1
export THINKTHEN_API_KEY=...
./run.sh my-rerunEvery system answers the same questions, and you can replay every answer for free.
On GitHub: github.com/botassembly/beatles-bench